Mark Gurman seems to get extraordinarily accurate and detailed leaks. I wonder how Apple got this leaky. Pretty much everything about the Duo was known months in advance.
Well, either corporate security got incompetent or they intentionally let select leaks exist to "test the market response". Established companies tend to get more risk averse overtime.
Has anyone have good success using AI generated CAD parts? I’ve been trying but it’s always 95% there, but with all hardware, you need 100% right. It’s often quicker and cheaper for me to do it by hand (but I was a mechanical design engineer for about a decade prior)
Just this morning I used OpenSCAD for the first time. I got Gemini (just the chatbot, no harness or MCP) to help me design a water-bowl holder for our senior dog (she kept knocking it over).
It was probably an easy model to get right, since the only "critical" dimension was the radius of the interior. But I was able to tweak the numbers on the support length & some other details relatively easily, and I had a working solution 2 hours of print time later.
(I had a CAD class in highschool, but haven't used it since).
I suspect this may be another case of "LLMs are mainly good at things you're bad at."
assemblies and tolerances are where AI generation quickly gets hard. but, for simpler things, it can be surprisingly good, especially for people who has no CAD knowledge. it certainly might feel a bit like brute-forcing through the LLM - but this also applies to vibe-coding..
I heard this was a thing when listening to a Theo podcast, he mentioned to add a "Only use subagents if the user explicitly requests them" line in your agents.md file.
I don't know if it works, but I've always had a consistent level of token burn on my plans (I've only heavily used Sol after adding it).
I’m more curious how each 4 bit quant compares. It seems like NVFP4 outperforms Q4_K_M in terms of speed and top 1 but is only good for expensive Nvidia cards
I swear, Qwen 3.8 27B @ Q8 is smarter than Sonnet 5 most of the time. Why wouldn’t corporate America self host at this point, especially with better options like Deepseek Flash and GLM 5.3 flash that’s a middle ground between Sonnet and Opus
Agreed. And conversely, American models can also just as easily be secretly influenced for bad things, or be more tightly controlled by the government, to corporate America's own detriment.
It's wild that people are so lost in the sauce of social media that they have no qualms handing over all their data to an authoritarian ethno state with a single ruler who appointed themselves for life with unrestricted unilateral control over every aspect of the state. And here we are calling for collapse because mom might get recommended Gain instead of Tide.
The context here of comparing trust between American models (which are mostly centrally hosted) to Chinese models (rather than "local" models) implies trust levels in who is hosting.
American local models don't hand over data either, which would nullify the point of the comment.
For most people around the world America is more of a threat than China. Heck for most Americans the American government is more of a threat than the Chinese government.
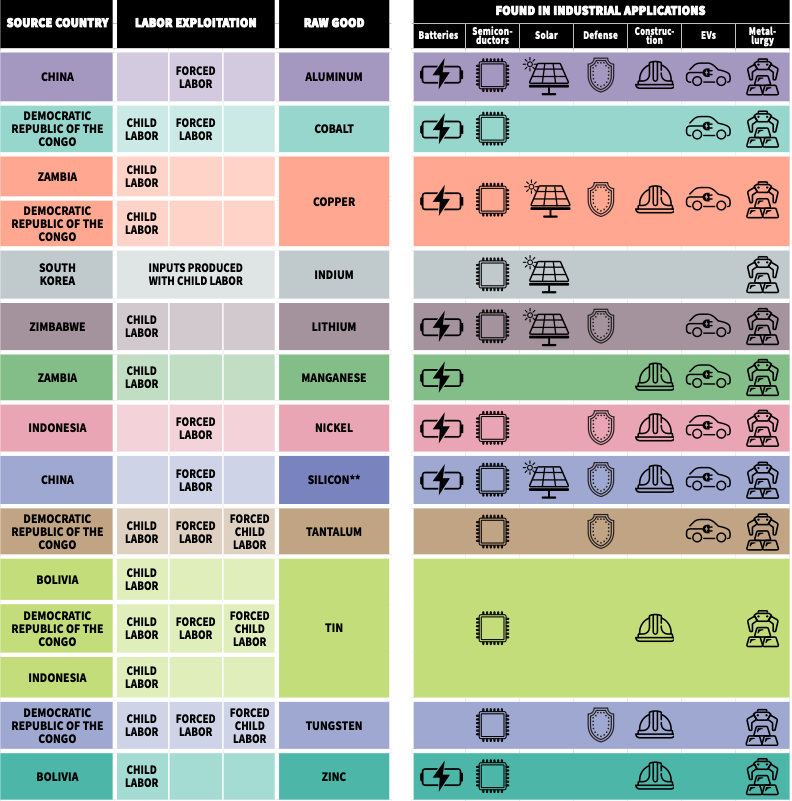
What's even more wild to me is that basically ALL modern electronics and all modern batteries are made from raw materials sourced by forced and child labor (and sometimes both)... yet the vast majority of the entire world just turns a blind eye to it.
This is very confused, first the world does not turn a blind eye, and by having US purchasers of these products the US is actually forcing a big change in the standards for the better due to purchasing power. In particular the US has avoided huge amounts of potential purchase in solar, largely under the justification of avoiding forced Chinese labor.
Second, the "ALL" qualification is extremely wrong, as only small fractions of these products in the US could ever be sourced to the human rights violations cited here.
From whence shall we expect the approach of danger? Shall some trans-Atlantic military giant step the earth and crush us at a blow? Never. All the armies of Europe and Asia...could not by force take a drink from the Ohio River or make a track on the Blue Ridge in the trial of a thousand years. No, if destruction be our lot we must ourselves be its author and finisher. As a nation of free men we will live forever or die by suicide.
― Abraham Lincoln
Still a ton of non tech companies doing a digital / tech transformation out there too lol. Maybe some so far behind they still have the real estate and rack space to get ahead on this one
I’m honestly surprised this is better benchmark wise than the text only model. I figured the addition of vision would take away from some of the text capabilities.
Tangentially this makes me wonder how large Opus really is. Perhaps Opus is a lot smaller than most of the 1T+ assumptions, just a lot more post-training/ finetuning on a 300-400B sized MoE model.


reply